Last week, TypeSafe AI released Jev, its first System One model. Founder Diogo Almeida previously worked at OpenAI on the instruction-following research behind ChatGPT.
Jev does not chat, write code or summarize. It takes unstructured state and returns typed decisions with calibrated probabilities. That makes it a natural fit for the thousands of small judgments inside an agent loop: which model to call, whether a command is safe, which passage is relevant, whether the agent is actually done.
How Jev Works
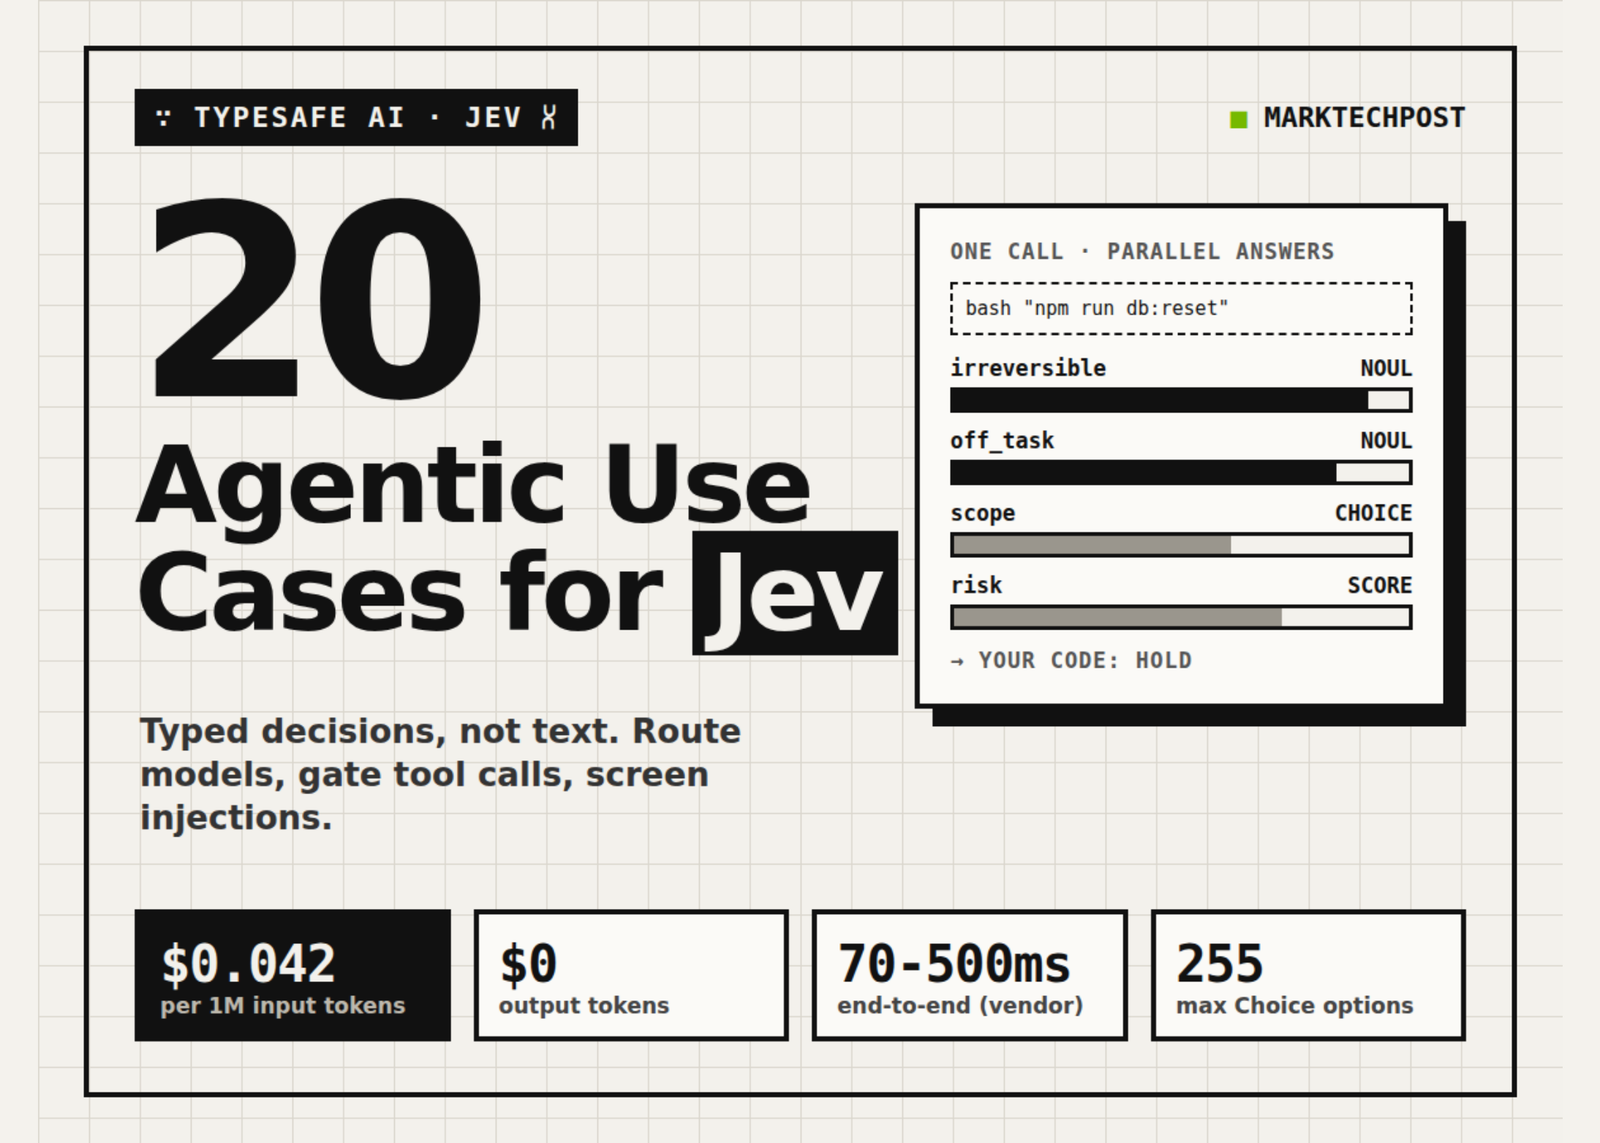
Every call sends a state (text or JSON) plus a dictionary of typed questions. TypeSafe’s docs define 3 primitives:
- Choice picks one option from a list and returns a probability per option plus confidence.
- Score rates the state on ordered rubric levels and returns probabilities plus confidence.
- Noul returns the probability (0 to 1) that a statement is true.
All questions are evaluated in parallel against the same state in one request. TypeSafe trains Jev with Reinforcement Learning for Calibrated Decisions (RLCD), so higher confidence should track higher accuracy. Choice supports up to 255 options.
The main claims, 193.6x faster and 444.6x cheaper, come from TypeSafe’s own workflow evals. The launch post says these figures sit on the higher end of real-world gains and use GPT-6 Astra and Fable 5.1 as the reference answer.
Interactive Explainer
Race a token-by-token LLM against Jev’s single pass, move a confidence threshold to see how code gates each decision, estimate monthly cost, and browse all 20 use cases.
20 Agentic Use Cases for Jev
Routing and orchestration
Safety and guardrails
Retrieval and grounding
Computer, browser and real-time control
Agent quality and memory
Jev vs Closest Competitors
Open-model figures are self-reported by each project on its own harness, so treat them as directional. OpenRouter’s Banking77 test is the cleanest head-to-head: Jev was 3.3 points less accurate than Claude Opus 5, 13x faster at the median, and about 1/22 the cost.
Key Takeaways
- Jev returns typed Choice, Score and Noul answers with probabilities, never free text.
- TypeSafe lists $0.042 per million input tokens, free output, and 70 to 500 ms latency.
- Best agent fits: routing, tool-call gating, reranking, citation checks and injection screening.
- On Banking77, Jev scored 81.0% vs 84.4% for Claude Opus 5, at 13x lower median latency.
- Schema-safe does not mean correct: calibrate thresholds on your own traffic first.
FAQ
- What is Jev? Jev is TypeSafe AI’s first System One model. It returns typed Choice, Score and Noul answers with probabilities instead of generated text.
- Is Jev an LLM replacement? No. It sits beside an LLM. The LLM plans and writes; Jev handles bounded decisions such as routing, gating and verification.
- How much does Jev cost? TypeSafe lists $0.042 per million input tokens, with output tokens free.
- Can I run Jev locally? Not TypeSafe’s model. Open projects like Laya and kev implement the same /v1/systemone interface on your own hardware.
Asif Razzaq is the CEO of Marktechpost AI Media Inc.. As a visionary entrepreneur and engineer, Asif is committed to harnessing the potential of Artificial Intelligence for social good. His most recent endeavor is the launch of an Artificial Intelligence Media Platform, Marktechpost, which stands out for its in-depth coverage of machine learning and deep learning news that is both technically sound and easily understandable by a wide audience. The platform boasts of over 2 million monthly views, illustrating its popularity among audiences.